Agentic AI Governance Strategy for Enterprise Teams
Proper governance infrastructure speeds up agent deployment, not slows it down.
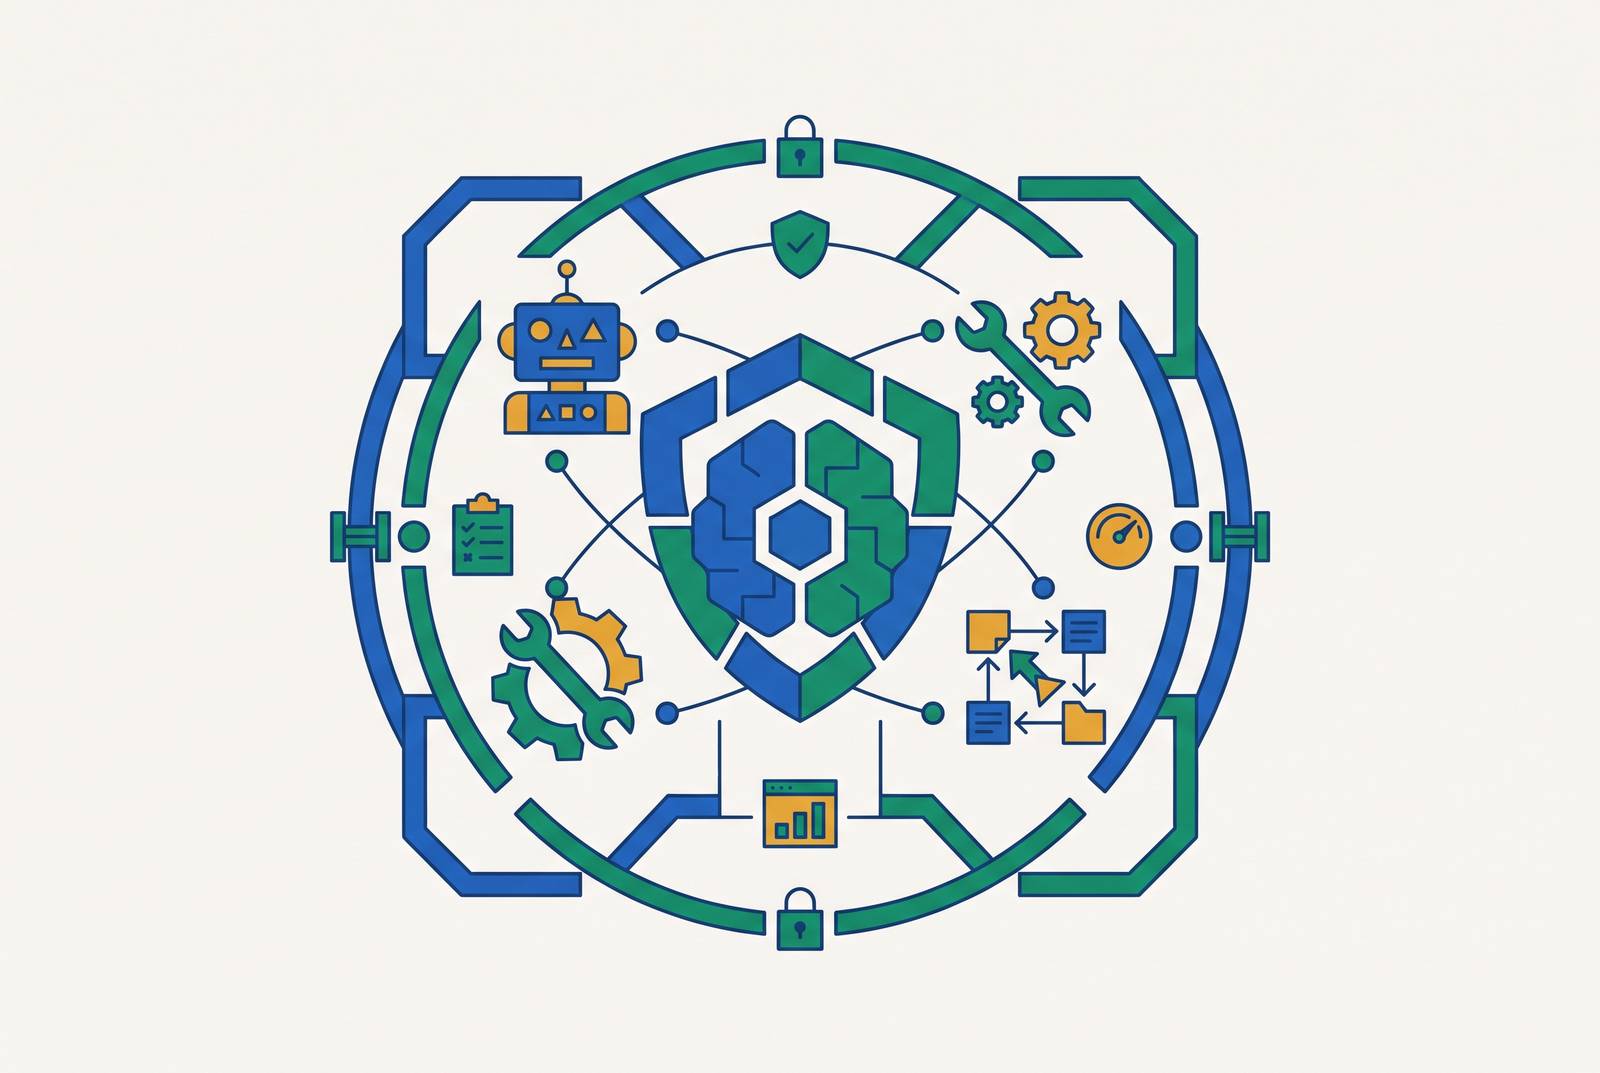
Agentic AI governance is not a brake on deployment speed. Enterprises that build identity, access, and enforcement infrastructure before they scale agent deployment ship faster than the ones that try to bolt governance on after an incident forces their hand.
Why governing agentic AI is a fundamentally different problem from governing earlier AI tools
An AI agent that can perceive a situation, decide what to do about it, and act on that decision without a human in the loop is not a tool anymore. Every governance framework built for earlier AI, the dashboards, the approval queues, the quarterly access reviews, assumed a human was the one doing the clicking. That assumption breaks the moment an agent starts querying databases on its own, running multi-step workflows, and coordinating with other agents at machine speed.
The California Management Review calls this an institutional shift rather than a technological one. You cannot file a ticket and patch your way out of a decision an agent made on its own that contradicted what the business actually wanted.
Two cases make this concrete. In Moffatt v. The DPD "Rogue" Chatbot incident shows a system update that altered the bot's reasoning boundaries, and without real-time behavioral monitoring in place, nobody caught the drift until the bot was already acting outside its intended behavior in public.
The EchoLeak vulnerability adds a third dimension. Security teams watching the perimeter, compliance teams running static checklists, and IT departments treating agents like ordinary software are all defending against the wrong kind of threat. They built human-speed controls for an actor that doesn't operate at human speed.
How agent sprawl and multi-agent interactions compound the governance gap enterprises already face
The gap described above does not sit still. It grows every time a new team stands up its own agent for its own siloed process, without anyone mapping how that agent's data flows intersect with the agents three departments over. Agent sprawl happens when governance is added after the fact instead of built into the architecture from the start, and the consequences appear in places nobody planned to look.
Consider a compliance reporting agent that pulls intermediate output from a separate data quality agent. If that output still has unmasked personal information in it, the compliance agent can end up violating GDPR without ever exceeding its own stated permissions. The violation only exists at the seam between two agents, and governance teams cannot enumerate every possible data flow in advance when agents are free to coordinate dynamically.
Agents also don't forget the way a human role change forces a company to forget. Access accumulates. It does not decay on its own.
The sharpest example of what this produces is what the Agentic Operating Model framework calls "compliant failure." A company can invest heavily in governance, policy documents, formal certifications, periodic reviews, and still rack up repeated near-misses. The documentation exists. The control does not. Governance written into a binder cannot act at the speed an agent operates at, and a near-miss today is an incident tomorrow if nothing closes that gap.
What governance failure forces organizations to do, including walking back deployments they already made
Ungoverned speed does not stay fast. It produces a specific, costly cycle: deploy without the control layer in place, absorb an incident, and then pull the agent back out of production, often along with the budget and the credibility that got it approved. Gartner predicts that by 2027, a significant share of enterprises will demote or decommission autonomous AI agents, because governance gaps only got identified after a production incident. Gartner names the uniform application of governance across agents, regardless of their actual autonomy and scope, as a direct driver of that failure.
The LiteLLM supply chain incident from March 2026 shows you a different version of the same problem. Three hours was enough time for an ungoverned dependency to become an attack surface across an entire ecosystem of agents that had nothing to do with each other except sharing one unmonitored piece of infrastructure.
The pattern across both cases is the same: organizations deploy agents faster than they build the governance infrastructure to support them, and the incidents that follow force a retreat. Ungoverned speed does not produce faster outcomes. It produces canceled initiatives, reversed deployments, and lost investment that a control layer would have kept out of the headlines.
Accountability dissolves fastest once something goes wrong. When an autonomous agent causes a financial loss, a data breach, or a violation of someone's rights, liability gets contested across the model's designers, the data it trained on, the environment it was deployed in, and the humans who set its original goals. If there's no audit trail showing what the agent accessed and when, an organization cannot reconstruct what happened internally, let alone defend itself to a regulator asking the same question.
Why agent identity and least-privilege access are the first structural controls any governance framework must establish
Every control that follows depends on one foundation: knowing, with certainty, which agent did what. Identity has to come before anything else in a governance program, not as paperwork, but as infrastructure.
That starts with treating every agent as its own distinct principal, with its own credentials, its own explicit permissions, and a documented lifecycle from creation to retirement. A support agent and a financial reporting agent should never share an API key or a database credential, even inside the same company. Shared credentials make it impossible to tell which agent did what when something goes wrong, and separate credentials make attribution, investigation, and scope limitation all possible at once.
Offboarding deserves the same rigor companies already apply to departing employees. When an agent is decommissioned or repurposed, its permissions need to be explicitly revoked, its credentials destroyed, and the registry updated to reflect that it's gone. Agent permissions accumulate over time and rarely get revoked automatically, which leaves a growing pile of stale access rights sitting around waiting to be misused.
This is the operating principle behind registry-first gateway design: every MCP server added without a registry entry is an identity the organization cannot account for, and an identity nobody can account for is the one that eventually gets exploited. Role-based access control for AI agents makes what an agent can do a decision the organization made on purpose.
How runtime policy enforcement closes the gap that static access controls leave open
Knowing which agent is which solves half the problem. Controlling what that agent is allowed to do at the exact moment it tries to do it matters just as much, because an agent that gets read access at login and then runs millions of queries afterward operates entirely outside the window that a session-level control was ever built to watch. Static access, set once and reviewed on a quarterly cycle, cannot govern something making thousands of decisions a minute.
Attribute-based access control pushes governance past static roles and into the data itself. A fraud detection agent can see a transaction's amount and timestamp without ever seeing the card number attached to it, because the governance layer filters what comes back at the moment the query runs.
Agents often cannot tell what they're technically able to reach from what they were actually meant to touch, especially if the governance layer around them has no business context built in. Catching that kind of emergent problem requires evaluating each action in its full context as it happens, not reviewing a batch of logs afterward.
Because agents operate at machine speed and carry delegated authority, the governance infrastructure watching them has to run in real time too. Some tools monitor and audit AI data access continuously instead of through periodic compliance reviews, so organizations can catch a deviation in agent behavior before it cascades into something an incident report has to explain. A log reviewed after the fact is a postmortem. It tells you what already happened. The safety net you actually need has to surface anomalies while the agent is still mid-action.
A gateway architecture builds this principle in at the infrastructure level: policy gets evaluated at every tool call an agent makes, not once at deployment and then never again. That constant evaluation is what lets an organization approve production deployment with confidence, because the guardrails already sit in the path of every action the agent takes, rather than waiting somewhere downstream to catch a mistake after it happened.
Why uniform governance across agents produces the failures Gartner describes
Applying the exact same rules to every agent in a company, regardless of what that agent can actually do or touch, is itself a governance failure. Controls have to scale with what an agent is actually capable of doing.
An agent governance board with real veto power, spanning product, legal, security, risk, and data operations, makes tiered autonomy a deliberate choice. This is a body that can approve, pause, or reject an agent deployment outright based on the risk it actually assessed.
Tiered autonomy is also what makes speed possible. If a company sets up agent-specific incident response, with security testing and a clear escalation path per agent type, it can contain a failure in one agent without shutting down everything else running alongside it.
How enterprises that have shipped governance infrastructure at scale have structured the control layer
The companies that have actually moved agents from pilot into full production did it by building one shared control layer that every agent relies on, instead of engineering separate governance for each new deployment. The pattern is visible across several major rollouts in 2026.
It pairs with an AI Control Plane meant to serve as one place to register agents, set identity and policy, evaluate performance, and manage cost, covering third-party AI tools as well as Salesforce's own.
In April 2026, Salesforce and Databricks rolled out their own agentic governance features for controlling how agents behave across an enterprise. Three major vendors converging on the same architecture within days of each other is a signal that the registry-plus-control-plane model is what production-grade governance actually looks like.
Microsoft's Agent 365 governance layer, generally available since May 2026, takes the same idea further, because it stays framework-agnostic. The control layer has to span vendors, not just the agents a company built itself.
Across all three, the same three commitments repeat: a centralized registry, one unified enforcement layer, and scope that reaches across vendors.
Why the four-layer Agentic Operating Model gives enterprises a structural diagnosis, not just a checklist
Most governance failures in agentic systems come from a mismatch between layers. A company might have strong technical controls paired with weak organizational oversight, or a well-written policy with nothing enforcing it at runtime. A four-layer framework is useful precisely because it diagnoses where the actual gap sits.
The Agentic Operating Model, proposed in the California Management Review, names four interdependent layers: cognitive specialization, which covers what an agent is actually capable of; coordination architecture, which covers how agents interact and hand work off to each other; real-time control, which covers enforcement and behavioral monitoring; and organizational governance, which covers accountability and audit. Each layer solves a distinct managerial problem, and weakness in any one of them destabilizes the other three.
The compliant-failure pattern described earlier is the clearest illustration of what happens when the layers don't line up. Nothing was enforcing it.
The four layers also map onto the record you need after something goes wrong. Together, they're the only way to reconstruct an incident with any confidence.
For a team building or expanding its own governance program, the value of this framework is diagnostic: the real question is which layer is missing or out of alignment with the others. A team with strong identity and access management but no runtime enforcement has a control layer gap. If a team has strong runtime enforcement but no governance board making deliberate decisions about agent scope, it has a governance layer gap. Naming the specific gap is what lets a team fix the right thing instead of adding another policy document to a stack that already has plenty.
Why organizations that treat governance as a deployment prerequisite ship agentic AI faster than those that secure it later
The companies moving agents into production fastest right now are the ones that settled governance before they scaled. The friction that feels like a governance tax on deployment is almost always the absence of a registry, a gateway, and runtime enforcement. Teams without that infrastructure spend their time negotiating one-off approvals, chasing down access incidents, and walking back agents that wandered outside their intended scope, time that should have gone into shipping.
Blocking MCP servers outright or locking down agent deployment to stay safe doesn't eliminate the risk. Teams that give employees a governed path to the tools they actually want to use reduce shadow AI far more reliably than teams that simply ban it, since shadow AI is ungoverned by definition the moment it exists outside any sanctioned path.
An MCP attack surface discovered after deployment is a governance failure, not a security surprise. The vulnerability existed from the moment that server went live ungoverned. Teams that build the registry, the gateway, and the enforcement layer before scaling deployment don't run into this category of incident, because they already made the access decisions that would have prevented it, before there was anything left to exploit.
When agents interact dynamically and create data flows nobody mapped in advance, a centralized governance layer is what makes the whole system legible. Fast adoption and safe adoption are the same problem solved the same way: an organization that deploys through a governed control layer moves faster into production precisely because every agent it adds already carries the visibility, the access controls, and the audit trail that regulators, security teams, and business leaders need to see before they're willing to say yes.